
A.1 Variables
Variables are the nodes in the computation graph. Below are the most important attributes of Variables:
1. Value is the unstructured data that the variable contains. Throughout this manuscript, all values are text data.
2. Role description is an informative string that describes the role of the variable in the computation graph. We use these roles to let the user inject knowledge into the graph and guide the optimization behavior. More information is described below.
3. Gradients are the natural language feedback provided by the LLMs during the backward pass. These describe the changes to make the variable so that the downstream loss can be improved. For an example backward operation that populates gradients, please read Section A.3.
4. Predecessors are the set of variables that are used to generate a given variable. For instance, if we are giving an instruction to an LLM and getting a response, the instruction would be the predecessor of the response. During the backward pass, the gradients on the successor are passed to its predecessors, to provide guidance around how to improve the downstream objective.
5. Requires grad indicates whether or not the gradients will be populated during the backward pass, analogous to PyTorch. For instance, if the user does not wish to compute gradients for a question, then simply write Variable(value=question, requires_grad=False, ...) to indicate this.
Role Description: In TEXTGRAD, each variable has a role description. In particular, this is a string that describes the role of the variable in the computation graph, such as system prompt to the language model or prediction by the language model. While sometimes populated automatically, in general role descriptions are one of the primary ways to inject user knowledge into the optimization process.
Empirically, we find that role descriptions can significantly steer the optimization process. For instance, setting the role of a prediction to be the final numerical answer to the language model guides the Textual Gradient Descent optimizer, that prompts a language model to update the value of the variable using the feedback, to update the variable such that it is only a numerical value. In comparison, a role description such as the reasoning for the solution and the final prediction guides the optimizer to produce the reasoning along with the final prediction.
Here is an example usage:
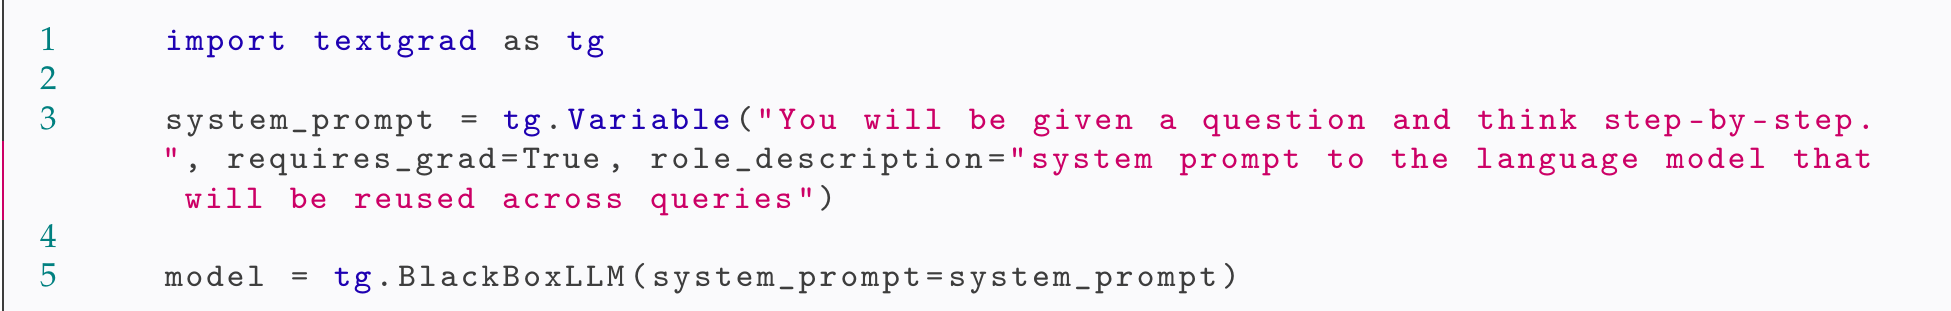
Code Snippet 3: An example usage of a role description.